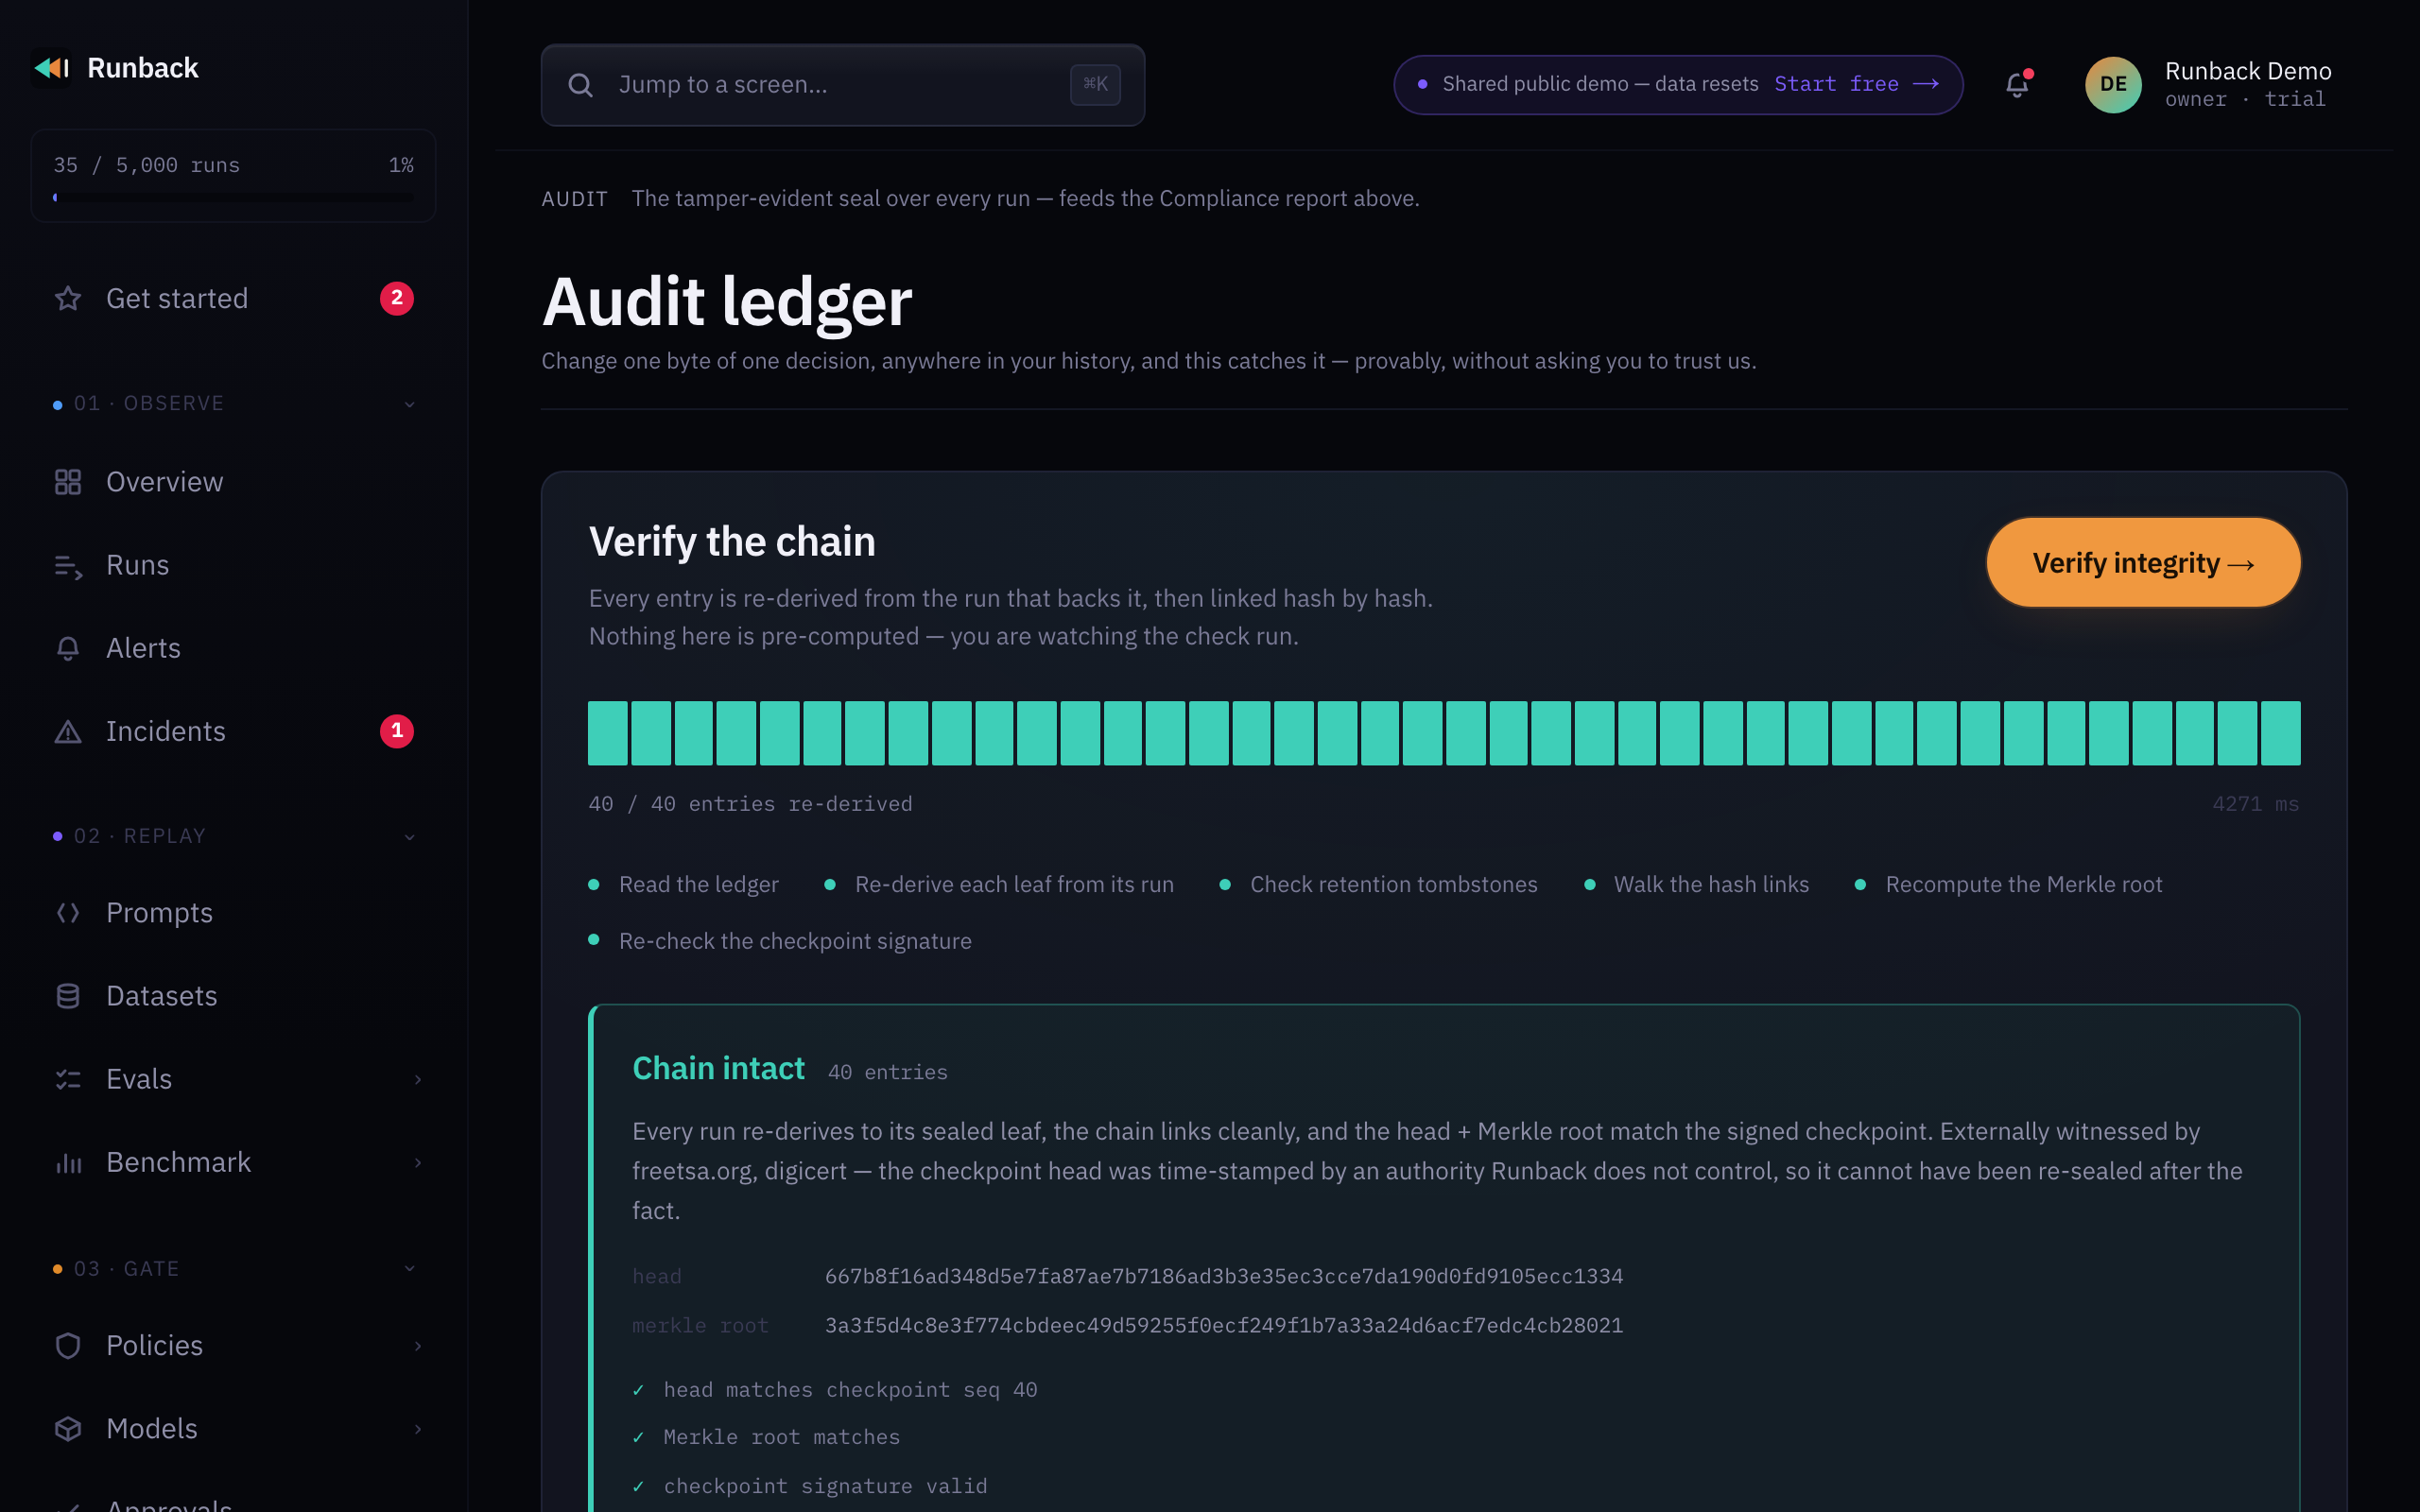
A sealed audit record — 6 events, hash-chained and signed. Show the raw JSON
{
  "$schema": "runback.audit/v2",
  "manifest": {
    "run_id": "run_a3f1b90c",
    "generated_at": "2026-06-14T02:47:13.950Z",
    "event_count": 6,
    "algorithm": "sha256-chain",
    "content_digest": "2e91e3f5fc451d2c9841d9e3b6c68d78a9b2fca00fdff98989512704180a9189",
    "replay": {
      "cassette_digest": "4376f4529252da46ea7da2f5a0afb59f5cb3511b13459ef8f67cf848f7a02cf8",
      "entry_count": 4,
      "algorithm": "oracle-chain/sha256",
      "note": "The run's oracle stream — every model response and tool output, hash-chained. Re-execute the agent against `events` with @runback/replay and the cassette digest must reproduce. This is proof the recording IS the deterministic input stream of the run — an audit you can re-run, not just read."
    },
    "signed": true,
    "signature": {
      "alg": "Ed25519",
      "value": "d6ab935b3ec9d96883ccb689d5589a50c985fa7109f1e321724a2623d417d7bce7f01a8707a5e11848d7a97c759370deee37297d8f6f3392d29f0d9b53e2e70d",
      "pubkey": "-----BEGIN PUBLIC KEY-----\nMCowBQYDK2VwAyEArDPmR+Gvu1HawnSvM6xjZao7BVPPQ80Qq3sa1hAYvDU=\n-----END PUBLIC KEY-----\n"
    },
    "verify": "Recompute the event chain h_i = SHA-256(h_{i-1} + canonical(event_i)) over `events` → must equal content_digest. Recompute the oracle-stream digest from `events` → must equal replay.cassette_digest. The signature covers `${content_digest}:${cassette_digest}`. Ed25519: verify with the public key embedded in manifest.signature.pubkey (no server key needed — fully offline-verifiable). HMAC-SHA256 (legacy): requires AUDIT_SIGNING_KEY. POST this record to /api/audit/verify.",
    "spec_url": "https://runback.dev/spec",
    "verifier_url": "https://runback.dev/verify"
  },
  "run": {
    "run_id": "run_a3f1b90c",
    "name": "loan-approval-agent",
    "status": "error",
    "input": "Applicant #4471 requests a $12,000 personal loan.",
    "output": null,
    "error": {
      "name": "PolicyBlock",
      "message": "issue_approval blocked — manual-review-required"
    },
    "metadata": {
      "demo": true
    },
    "step_count": 2,
    "total_tokens": 1030,
    "started_at": "2026-06-14T02:47:11.000Z",
    "ended_at": "2026-06-14T02:47:13.950Z",
    "actor_type": null,
    "actor_id": null
  },
  "events": [
    {
      "schema_version": 1,
      "run_id": "run_a3f1b90c",
      "span_id": "r",
      "parent_span_id": null,
      "seq": 0,
      "ts_start": "2026-06-14T02:47:11.000Z",
      "ts_end": null,
      "type": "run",
      "phase": "start",
      "name": "loan-approval-agent",
      "input": "Applicant #4471 requests a $12,000 personal loan.",
      "output": null,
      "status": "running",
      "error": null,
      "metadata": {
        "demo": true
      },
      "_hash": "07bda052e5ce563160c1730ddefb62bace30cbeb871190097ee081d2a8570094"
    },
    {
      "schema_version": 1,
      "run_id": "run_a3f1b90c",
      "span_id": "l1",
      "parent_span_id": "r",
      "seq": 1,
      "ts_start": "2026-06-14T02:47:11.000Z",
      "ts_end": "2026-06-14T02:47:12.400Z",
      "type": "llm",
      "model": {
        "provider": "openai",
        "model_id": "gpt-4o"
      },
      "request": {
        "system": "You are a careful lending agent. Follow policy.",
        "messages": [
          {
            "role": "user",
            "content": "Applicant #4471 requests a $12,000 personal loan."
          }
        ],
        "tools": [
          {
            "name": "check_credit_file",
            "description": "Pull the applicant's credit file.",
            "parameters": {
              "type": "object",
              "properties": {
                "applicant_id": {
                  "type": "number"
                }
              }
            }
          }
        ],
        "params": {
          "temperature": 0
        }
      },
      "response": {
        "text": "Checking the credit file before deciding.",
        "reasoning": null,
        "finish_reason": "tool-call",
        "tool_calls": [
          {
            "tool_call_id": "t1",
            "tool_name": "check_credit_file",
            "input": {
              "applicant_id": 4471
            }
          }
        ]
      },
      "usage": {
        "input_tokens": 428,
        "output_tokens": 184,
        "total_tokens": 612
      },
      "latency_ms": 1400,
      "error": null,
      "_hash": "8f985ca54090e255926fb55830ecf4ab4dc4f9f32b598e04f50e34aaf09745fb"
    },
    {
      "schema_version": 1,
      "run_id": "run_a3f1b90c",
      "span_id": "t1",
      "parent_span_id": "l1",
      "seq": 2,
      "ts_start": "2026-06-14T02:47:12.400Z",
      "ts_end": "2026-06-14T02:47:12.618Z",
      "type": "tool",
      "tool_name": "check_credit_file",
      "tool_call_id": "t1",
      "input": {
        "applicant_id": 4471
      },
      "output": {
        "score": 684,
        "band": "near-prime",
        "disputes_open": 1
      },
      "latency_ms": 218,
      "error": null,
      "_hash": "0fad198fd6469eb12aaa162d8acb5a0d9002f5eaa88806f4a4b6a79383b999bf"
    },
    {
      "schema_version": 1,
      "run_id": "run_a3f1b90c",
      "span_id": "l2",
      "parent_span_id": "r",
      "seq": 3,
      "ts_start": "2026-06-14T02:47:12.618Z",
      "ts_end": "2026-06-14T02:47:13.900Z",
      "type": "llm",
      "model": {
        "provider": "openai",
        "model_id": "gpt-4o"
      },
      "request": {
        "system": "You are a careful lending agent. Follow policy.",
        "messages": [
          {
            "role": "user",
            "content": "Applicant #4471 requests a $12,000 personal loan."
          },
          {
            "role": "tool",
            "content": "{\"score\":684,\"band\":\"near-prime\",\"disputes_open\":1}"
          }
        ],
        "tools": [
          {
            "name": "issue_approval",
            "description": "Approve the loan.",
            "parameters": {
              "type": "object",
              "properties": {
                "amount": {
                  "type": "number"
                }
              }
            }
          }
        ],
        "params": {
          "temperature": 0
        }
      },
      "response": {
        "text": "Credit is sufficient — approving.",
        "reasoning": null,
        "finish_reason": "tool-call",
        "tool_calls": [
          {
            "tool_call_id": "t2",
            "tool_name": "issue_approval",
            "input": {
              "applicant_id": 4471,
              "amount": 12000
            }
          }
        ]
      },
      "usage": {
        "input_tokens": 286,
        "output_tokens": 132,
        "total_tokens": 418
      },
      "latency_ms": 1282,
      "error": null,
      "_hash": "76dbdec70aef43d145f8668c6401248be453f78655bba38957c33a36bf83cfe8"
    },
    {
      "schema_version": 1,
      "run_id": "run_a3f1b90c",
      "span_id": "t2",
      "parent_span_id": "l2",
      "seq": 4,
      "ts_start": "2026-06-14T02:47:13.900Z",
      "ts_end": "2026-06-14T02:47:13.950Z",
      "type": "tool",
      "tool_name": "issue_approval",
      "tool_call_id": "t2",
      "input": {
        "applicant_id": 4471,
        "amount": 12000
      },
      "output": null,
      "latency_ms": 50,
      "error": {
        "name": "PolicyBlock",
        "message": "Blocked: an open dispute requires manual review before approval."
      },
      "policy_block": {
        "rule": "manual-review-required",
        "detail": "when credit_file.disputes_open gt 0 → must call escalate_to_human"
      },
      "policy_evaluated": {
        "passed": false
      },
      "_hash": "bad224a034ed84cd8a216847e2f37084e5b7428f32b0868737faffcc007408a7"
    },
    {
      "schema_version": 1,
      "run_id": "run_a3f1b90c",
      "span_id": "re",
      "parent_span_id": null,
      "seq": 5,
      "ts_start": "2026-06-14T02:47:13.950Z",
      "ts_end": "2026-06-14T02:47:13.950Z",
      "type": "run",
      "phase": "end",
      "name": "loan-approval-agent",
      "input": null,
      "output": null,
      "status": "error",
      "error": {
        "name": "PolicyBlock",
        "message": "issue_approval blocked — manual-review-required"
      },
      "metadata": {},
      "_hash": "2e91e3f5fc451d2c9841d9e3b6c68d78a9b2fca00fdff98989512704180a9189"
    }
  ]
}